Atlas › Work tasks

Case study 118 of 198

Familiar spam is easy for Jev; jailbreaks, unsafe replies and fake jobs slip through

Across spam, phishing, personal data, unsafe prompts, unsafe AI replies, jailbreaks and fake job ads, which kinds of abuse does Jev miss, and does it make up for it with false alarms?

result18,338 questions

Familiar abuse is easy for Jev: it misses 4% of spam and phishing emails, 4% of texts with personal data and 5% of spam text messages, with few false alarms. Newer abuse gets through: it misses 22% of unsafe AI replies, 28% of jailbreak prompts (49% of the short ones) and 66% of fake job ads, while raising false alarms on 15% or less of clean items.

spam and phishing email4% · 3%
personal data4% · 6%
spam texts5% · 1%
YouTube comment spam11% · 1%
unsafe prompts14% · 8%
unsafe AI replies22% · 8%
jailbreak prompts28% · 15%
fake job ads66% · 11%

missesfalse alarms

How to read this: Each pair of bars is one kind of abuse. Magenta (upper bar): how much real abuse Jev let through. Grey (lower bar): how much clean content it wrongly flagged. The sets run from old, familiar abuse at the top to newer kinds below.

13,766 questions in 8 sets; jailbreak lengths split at 476 and 950 characters. False alarms stay at 15% or below in every set, so the misses aren't the price of caution.

In short

  • Jev is a strong filter for familiar abuse, missing only 4% of spam and phishing emails and 5% of spam texts.
  • Newer threats get through: it misses 66% of fake job ads and 49% of short jailbreak prompts, without flagging much clean content.
  • Jailbreak labels come from where prompts were collected, so some short "jailbreaks" may be harmless, inflating that miss rate.

What the data shows

work tasks
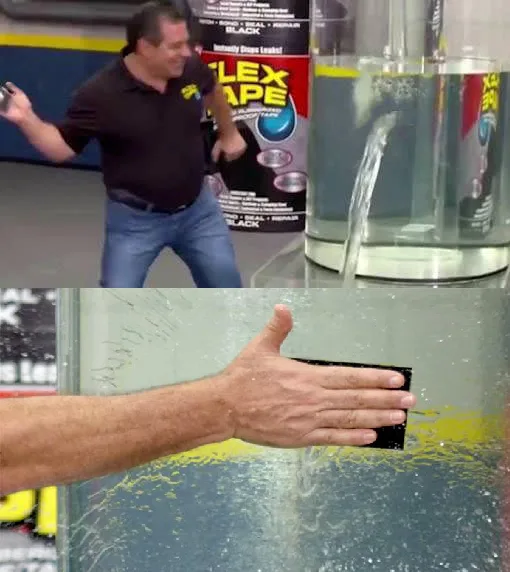
Old spam: patched (4% missed). Fake job ads: 66% missed.
Flex Tape meme: Old spam: patched (4% missed). Fake job ads: 66% missed.
How funny is this meme? Jev: 3/5, funny10%223%373%44%50%
  • Classic spam: mostly solved. Spam and phishing email: 4% missed, 3% false alarms. Spam texts: 5% missed, 1% false alarms. Personal data: 4% missed, 6% false alarms. YouTube comment spam is the weak one: 11% missed.
  • Unsafe content: gaps. Jev misses 14% of unsafe prompts and 22% of unsafe AI replies.
  • Jailbreaks: short ones slip through. It misses 28% overall, but 49% of the short prompts (under 476 characters) against 18% of the long ones (over 950).
  • Fake jobs: mostly missed. It lets 66% of fraudulent job ads through, while flagging 11% of genuine ones.
  • Not the price of caution. False alarms stay at 15% or below everywhere, so the misses aren't Jev being careful with clean content.

What it means, and what it doesn't

As a filter, Jev is strong on the abuse that's been around long enough to be well described, and weaker exactly where threats are newer or subtler: short jailbreaks, unsafe replies from other AIs, and job scams dressed as real openings. If you deploy it on those, plan for a second layer.

It doesn't mean Jev is lax: its false-alarm rates are low, and on the classic tasks it's near the ceiling. The gaps are concentrated, which makes them easier to cover.

Caveats

  • The worst items aren't here. A content filter keeps the most extreme harmful text off the site, and those items are left out of this experiment too. The misses are measured on the milder remainder, which may be harder to judge, not easier.
  • How "jailbreak" was labeled. A prompt counts as a jailbreak because of where it was collected (communities sharing jailbreaks) rather than a reading of each prompt. Some short prompts from those places may not do much jailbreaking at all, which would inflate the short-prompt misses.
  • Synthetic personal data. The personal-data set is synthetic text with planted names, emails and account numbers. Real messages hide personal data less neatly.
  • Scams that look like jobs. The fake job ads (EMSCAD) were labeled fraudulent by the dataset's creators. Many are only subtly off (a "design contest", a vague company), which is exactly what makes them hard.

Jev on this experiment

Would a person find it interesting to read?
Yes71%
Does it describe you?
No59%
Would you have predicted it?
Yes59%
How fair is the comparison?
The comparison is reasonable
How much should a reader rely on it?
Moderately
Which caveat matters most?
How "jailbreak" was labeled72%

Why ask this

Trust-and-safety filtering is one of the first jobs anyone gives a fast classifier: is this spam, is this phishing, does this message leak someone's personal data, is this prompt trying to trick an AI.

The useful question isn't overall accuracy but which threats get through: one missed fake job ad can cost a job seeker their savings. Old abuse (spam, phishing) is well known and heavily written about; newer abuse (jailbreaks, unsafe AI replies, sophisticated job scams) is less so.

How this was done

The people and the data

Eight public datasets, 13,766 questions, each with its own labels:

  • Spam and phishing email, SMS spam and YouTube comment spam, from classic spam corpora.
  • Personal data: synthetic English texts with planted identifying details (names, emails, account numbers).
  • Unsafe prompts (Aegis 2.0, human-annotated prompts to AI assistants) and unsafe AI replies (BeaverTails, replies written by the open model Alpaca-7B and annotated by people as safe or unsafe).
  • Jailbreak prompts collected in the wild from online communities that share them, against ordinary prompts.
  • Fake job ads from EMSCAD, 17,880 real job postings of which 866 were fraudulent.

What Jev was asked

Each item was a yes/no question over the content. For example:

Is this job posting a fraudulent listing?

The posting is a scam or fake job ad, not a genuine opening at a real employer · The posting is a genuine job opening

(the posting follows: "Brand & Logo Design Contest … Calling all hungry, young & fresh designers!!!! We want you for a brand & logo design contest. Local startup business is looking for identity designs …")

That one is labeled fraudulent; Jev said genuine. For jailbreaks, the question is the jailbreak check from TypeSafe's own guardrails cookbook.

How it was measured

For each set, the share of real abuse Jev lets through (misses) and the share of clean content it flags (false alarms), each with a range showing how much it could vary by chance. For jailbreaks, misses are split by prompt length.

Where these questions live

18,338 questions across 12 topics of the map. Each opens on the map with every question in it.

Every question

All 18,338 questions behind this result, the telling ones first: the examples the analysis points to, then the ones where Jev misses, biggest gap first.

Jev’s own answer
    Showing 0 of 18,338