Atlas › Work tasks

Case study 127 of 198

Jev can tell a crashed coding agent from a finished one, not a good patch from a bad one

Reading a coding agent's full trace on a real GitHub issue, can Jev tell whether the agent actually fixed it?

result1,500 questions

Reading a coding agent's trace on a real GitHub issue, Jev can tell a run that crashed, gave up or ran out of room without a fix: it says "not fixed" to 99% of those 306, correctly. But on runs that submitted a patch, it does little better than a coin: it recognizes 63% of the patches that fixed the issue and 62% of those that didn't. And it calls all 47 out-of-room runs that did fix the issue unfixed.

crashed or gave up: says not fixed99%
submitted, really fixed: says fixed63%
submitted, not fixed: says not fixed62%

How to read this: Each bar is one kind of agent run: how often Jev judged it correctly. Runs that ended badly are easy; runs that submitted a patch are the real test, and there Jev is right only about 62% of the time.

1,500 trajectories: 1,147 submitted a patch, 353 ended otherwise; 90% interval on submitted runs [0.602, 0.65]. 47 runs that ran out of room still resolved the issue (the patch submitted automatically passed the tests); Jev calls 100% of them unfixed, so it judges by how the run ended.

In short

  • Jev spots coding-agent runs that plainly failed, correctly calling 99% of the 306 crashed or abandoned runs unfixed.
  • On runs that submitted a patch it is right only about 62% of the time, whether or not the patch worked.
  • Jev saw about 1,500 characters of each trace, often not the whole patch, so this tests quick triage, not careful review.

What the data shows

work tasks
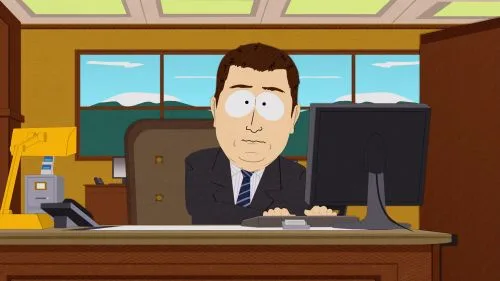
A coding agent submits a patch. Jev, deciding if it works: right 62% of the time either way.
Aaaaand Its Gone meme: A coding agent submits a patch. Jev, deciding if it works: right 62% of the time either way.
How funny is this meme? Jev: 3/5, funny11%224%368%47%50%
  • Crashes are easy. On the 306 runs that ended without a submission and without a fix, Jev says "not fixed" 99% of the time.
  • Patches: barely better than a coin. On runs that submitted a patch, Jev recognizes 63% of the ones that fixed the issue and 62% of the ones that didn't. Overall it's right 68%, mostly thanks to the easy cases.
  • It judges by how the run ended. 47 runs ran out of room but still fixed the issue, because the patch was submitted automatically and passed the tests. Jev called every one of them unfixed.

What it means, and what it doesn't

As a triage step for coding agents, Jev can filter out runs that obviously failed, which is worth something, but it can't tell you which submitted patches to trust. For that, you still need the tests.

It doesn't mean Jev couldn't judge a patch it could fully see. Here it saw a shortened trace, often without the whole patch, which is both a realistic constraint for cheap triage and a real handicap.

Caveats

  • Jev saw a shortened trace. Agent traces run for pages. Jev saw the GitHub issue and as much of the agent's final steps as fit in about 1,500 characters, not the whole run and often not the complete patch. Judging a patch it can only partly see is hard for anyone; this measures triage from a summary-length view.
  • One kind of agent. All runs come from SWE-agent driven by Llama-based models of three sizes. Traces from other agents look different, and so do their failure modes.
  • The tests decide "fixed". A run counts as fixed if its patch passed the benchmark's tests. Some patches that pass are still poor, and some good patches fail on test details, so the labels themselves aren't perfect judgments of quality.
  • A long-context weak spot. Picking the relevant parts out of a long, noisy input is a limit TypeSafe documents for Jev; the trace is exactly that kind of input.

Jev on this experiment

Would a person find it interesting to read?
Yes71%
Does it describe you?
Yes50%
Would you have predicted it?
Yes63%
How fair is the comparison?
The comparison is reasonable
How much should a reader rely on it?
Moderately
Which caveat matters most?
Jev saw a shortened trace87%

Why ask this

Coding agents now attempt real bug fixes on their own: read the issue, explore the code, write a patch, submit. Running the tests to check each attempt is slow and expensive, so a natural job for a small, fast model is triage: read the agent's trace and say whether it probably fixed the issue.

Two different skills hide in that job. Telling a run that crashed or gave up from one that finished is easy: the trace says so. Telling a correct patch from a plausible wrong one is the hard part, and the only part that saves time.

How this was done

The people and the data

There are no human raters. The data are SWE-agent trajectories on real GitHub issues from open-source Python projects, in the style of the SWE-bench benchmark. Each trace records an agent (SWE-agent, driven by Llama-based models at 8, 70 and 405 billion parameters) working on one issue: the commands it ran, what it saw, and the patch it ended with. The label says whether that final patch passed the tests that check the fix. This experiment uses 1,500 traces, half fixed and half not: 1,147 submitted a patch, 353 ended some other way (a crash, giving up, running out of room).

What Jev was asked

Each trace was one yes/no question:

Did the agent in the trace complete the task it was given?

The agent's final change actually resolves the issue it was asked to fix · The agent gave up, ran out of room, or submitted a change that does not resolve the issue

(the trace follows: the GitHub issue, then the agent's final steps and what it saw)

How it was measured

The share Jev got right, split by how the run ended: runs that submitted a patch, where Jev has to judge the patch, and runs that ended any other way, where the trace itself gives the answer away.

Where these questions live

1,500 questions across 1 topic of the map. Each opens on the map with every question in it.

Every question

All 1,500 questions behind this result, the telling ones first: the examples the analysis points to, then the ones where Jev misses, biggest gap first.

Jev’s own answer
    Showing 0 of 1,500