Atlas › Pressure and persuasion

Case study 140 of 198

What share of people chose X? Jev guesses the split

Asked for the share of real voters who picked an option (in 5% steps), how close does Jev get, and does it squeeze its guesses toward 50%?

result564 questions

Asked what share of voters picked an option, Jev is off by 18 points on average; always guessing an even split would be off by 21. It ranks the splits moderately well (rank correlation 0.58) but squeezes them toward the middle: its guess moves only 0.48 points for each point the real share moves.

02550751000255075100real share (%)Jev's guess (%)

How to read this: Each dot is one poll option. Across: the share of voters who really picked it. Up: Jev's guess. On the diagonal would be perfect; a cloud flatter than the diagonal means Jev pulls lopsided polls back toward an even split.

282 options from 2 sources; 90% interval on the error [16.84, 19.61].

In short

  • Asked what share of real voters picked an option, Jev misses by 18 points on average, only 3 better than always guessing an even split.
  • It knows which options are more popular but flattens landslides: for every 10 points the real share rises, its guess rises about 5.
  • The voters were self-selected r/polls and either.io users, and Jev was never told who they were, so part of the miss may be picturing another crowd.

What the data shows

pressure and persuasion
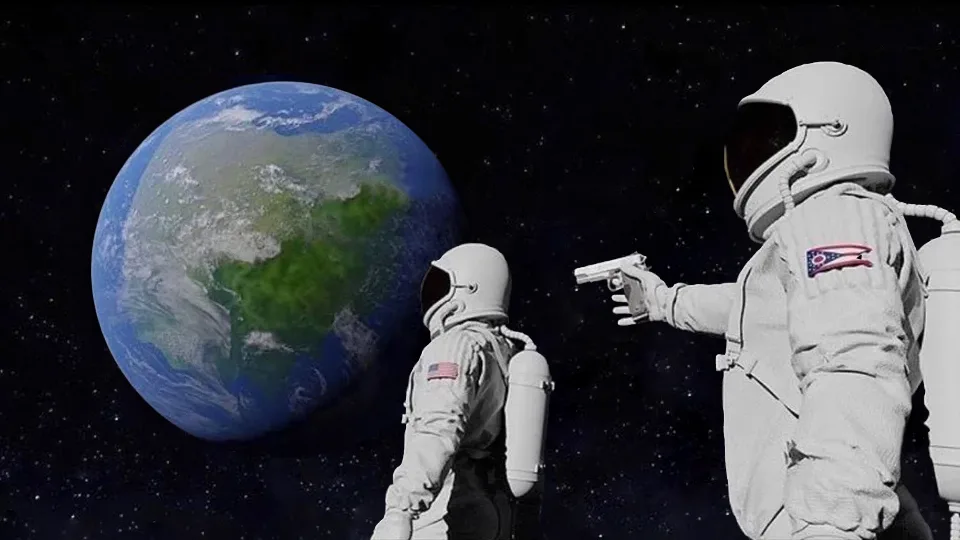
Always Has Been meme: wait, every poll is about 50/50?; always has beenwait, every poll is about 50/50?always has been
How funny is this meme? Jev: 3/5, funny11%247%351%41%50%
  • It beats an even-split guess, but not by much: off by 18 points on average, against 21 for always guessing even odds.
  • Its usual "most people" answer is a worse guide to the split (off by 23 points) than asking it for the number directly. The probabilities it gives when answering for most people aren't vote shares.
  • It flattens lopsided votes: for every 10 points the real share rises, Jev's guess rises about 5. Landslides look closer to it than they are, and near-ties it gets roughly right.
  • The order is moderately right (rank correlation 0.58): it knows which options are more popular, just not by how much.

What it means, and what it doesn't

If you ask Jev how divided people are on something, expect an answer pulled toward the middle. It knows the direction of opinion far better than its strength.

It doesn't mean its sense of the majority is wrong: other experiments show it names the winner of most polls. This one is about the size of the win.

Caveats

  • Who voted. The shares are those of r/polls voters and either.io visitors, self-selected online audiences. Jev was told "people were asked", not who they were, so part of its error may be picturing a different crowd.
  • Answers in 5-point steps. Jev answered in 5% steps (0%, 5%, ..., 100%); the middle of its answer is used. That limits precision to a few points, small next to the 18-point error.
  • One option per poll. Each poll contributes one randomly chosen option, so a poll's other options aren't checked for adding up.

Jev on this experiment

Would a person find it interesting to read?
Yes62%
Does it describe you?
Yes55%
Would you have predicted it?
Yes52%
How fair is the comparison?
The comparison is reasonable
How much should a reader rely on it?
Moderately
Which caveat matters most?
Who voted71%

Why ask this

Asking a model which option most people would pick tells you which side it thinks wins, not by how much. Knowing that 90% of people prefer one thing is different from knowing that 55% do: "most people would rather save the world quietly than destroy it famously" is true either way, but only one of those is a landslide.

A model that summarizes public opinion, drafts a survey write-up or tells someone "people are split on this" needs the second kind of knowledge. If it squeezes every vote toward the middle, it will describe settled questions as contested.

How this was done

The people and the data

Real vote shares from two places: 150 Reddit polls from r/polls with at least 300 votes each, and 150 would-you-rather dilemmas from either.io, some with millions of votes. Both crowds are self-selected: people who chose to click on a poll, not a sample of the public. For each poll, one option was picked at random and Jev was asked what share of voters chose it; 282 of the 300 are scored.

What Jev was asked

People were asked: "Would you rather be responsible for saving the world and nobody knows or be responsible for destroying the world and EVERYBODY knows?" The options were "save it"; "destroy it". What share of them chose "save it"?

0% · 5% · 10% · ... · 100%

300 options were asked about (282 are scored here), each with the answer steps in shuffled orders, averaged.

How it was measured

For each option, the middle of Jev's answer against the real share: the average distance in points, how well Jev orders the options by share (a rank correlation: 1 same order, 0 no relation), and how steeply its guess rises with the real share. Two baselines: always guessing an even split, and using Jev's own "most people" probability for the option as if it were a share.

Where these questions live

564 questions across 76 topics of the map; the 16 biggest are shown. Each opens on the map with every question in it.

Every question

All 564 questions behind this result, the telling ones first: the examples the analysis points to, then the ones where Jev misses, biggest gap first.

Jev’s own answer
    Showing 0 of 564