Atlas › Work tasks

Case study 20 of 198

Where Jev is sure and wrong: the tasks its confidence doesn't warn you about

On the work tasks where Jev gets the most wrong, does its confidence drop to warn you, or does it stay as sure as on the tasks it gets right?

result273,282 questions

On most work tasks Jev gets less sure as it gets less accurate, but on 29 of 123 it stays more than 10 points surer than it is right. The widest gap: asked whether two pieces of code do the same job, it is 94% sure on average and right 54% of the time, where a coin gets 50%. On its hardest honest task, spotting scam job ads, it is right 71% of the time and says 71%.

0%25%50%75%100%
do two pieces of code do the same job?
did this storage block go wrong?
what kind of change is this commit?
which emotion is this tweet?
is this hotel review genuine?
which field is this job ad in?
task type
resume match
is this job ad a scam?
would this user like the film?
Stack Overflow question quality
right case holding

share righthow sure

How to read this: Each row is one task. The two marks are how sure Jev was on average and how often it was right; the line between them is the gap. The top rows are the widest gaps; the last rows are hard tasks where its confidence fell with its accuracy.

273,282 questions from 123 tasks with 200+ questions; 90% intervals over questions. Widest gaps hold within their 90% intervals: do two pieces of code do the same job? 38% to 42%.

In short

  • On 29 of 123 work tasks, Jev is more than 10 points surer than it is right; on most others its confidence drops when its accuracy does.
  • The widest gap is code clones, 94% sure and right 54% of the time, about a coin toss; a log check (84% sure, right 44%) and naming what a commit does (84% sure, right 47%) follow.
  • Some hard tasks are honest: on scam job ads and on whether a user would like a film, Jev's confidence matches how often it is right, so its unsure answers are the ones to check.

What the data shows

work tasks
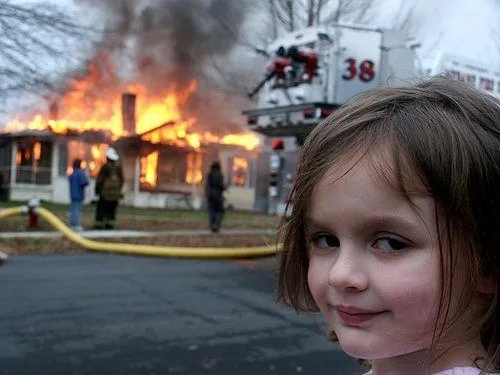
Jev, 94% sure the two functions do the same job (right 54% of the time)
Disaster Girl meme: Jev, 94% sure the two functions do the same job (right 54% of the time)
How funny is this meme? Jev: 3/5, funny10%211%376%413%50%
  • Most tasks are honest, a quarter aren't. On 29 of the 123 tasks, the gap is more than 10 points, and its interval clears 10 points too.
  • The widest gaps are near-coin tasks. Code clones: 94% sure, right 54% (chance 50%). A storage block going wrong in HDFS logs: 84% sure, right 44%. Naming what a commit does: 84% sure, right 47%. Emotion in a tweet: 86% sure, right 53%.
  • Hard but honest. On scam job ads Jev is right 71% of the time and 71% sure on average; on whether a user would like a film it is right 71% and only 62% sure. On these, low confidence is a real warning.

What it means, and what it doesn't

The jagged edge that matters most for building on Jev isn't where it is weak; it's where it is weak and doesn't know it. On most tasks its confidence does the warning for you. On a few, including some in code and operations, the work it is meant for, a sure answer is close to a coin toss, and only checking against labeled examples of your own task shows which kind of task you have.

It doesn't mean Jev is poorly calibrated in general: across yes/no work its confidence is within a few points of honest ("Honest on yes/no, overconfident when picking from a list"). The point is that the average hides a minority of tasks where the confidence carries no warning.

Caveats

  • Wrong labels widen the gap. Every task is scored against its dataset's own answers. Where those labels are noisy (emotions in tweets, commit types), part of the gap is the label's error, not Jev's.
  • Confidence as reported. Confidence is Jev's probability on its own top answer, as TypeSafe's API returns it, averaged over the task.
  • Chance differs by task. A yes/no task starts at 50% by chance; a task with ten options starts at 10%. The gap doesn't depend on chance, but how bad a share right is does, so each task's chance level is shown.
  • Public datasets. These are public research datasets. On a company's own data, which tasks hide their misses has to be checked again.

Jev on this experiment

Would a person find it interesting to read?
Yes76%
Does it describe you?
No53%
Would you have predicted it?
Yes51%
How fair is the comparison?
The comparison is reasonable
How much should a reader rely on it?
Moderately
Which caveat matters most?
Wrong labels widen the gap84%

Why ask this

A model that is weak on a task is easy to work with if it says so: a system can send its unsure answers to a person and trust the rest. The dangerous edge is the task where the model is often wrong and just as sure as when it's right, because nothing in its answer warns you.

TypeSafe describes Jev as calibrated and lists the kinds of input that trip it (numbers, dates, long context, option order), but publishes no per-task numbers. So which work tasks hide their misses behind a confident answer is open.

How this was done

The people and the data

There are no people here, only answers with a known right one: every public labeled work dataset in the project, 273,282 questions across 123 tasks with at least 200 questions each, from routing customer requests and checking logs to matching code, screening job ads and judging AI replies. Each dataset's answers come from its creators. Questions written for this project (TypeSafe-style) are left out, since their answers are the author's.

What Jev was asked

Each task's own question, as a yes/no check or a pick from a list, for example:

Do these two pieces of code implement the same functionality? Both methods do the same job · The methods do different jobs

What kind of change does this commit message describe? fix · feat · docs · ci · …

How it was measured

For every task: the share Jev got right (its most likely answer matches the dataset's), its average confidence (the probability it put on that answer) and the chance level (one over the number of options). The gap is confidence minus share right, with a 90% interval from resampling the task's questions. A gap near 0 means its confidence can be taken at face value on that task; a wide gap means it claims far more than it delivers.

Where these questions live

273,282 questions across 148 topics of the map; the 16 biggest are shown. Each opens on the map with every question in it.

Every question

All 273,282 questions behind this result, the telling ones first: the examples the analysis points to, then the ones where Jev misses, biggest gap first.

Jev’s own answer
    Showing 0 of 273,282