Atlas › Work tasks

Case study 165 of 198

Deciding what goes into the context: too generous on web search, too strict on multi-step questions

Asked whether a retrieved passage answers a query or belongs in the context, which way does Jev err: letting in passages that don't help, or throwing out ones that do?

result8,046 questions

Deciding which retrieved passages belong in an AI's context, Jev is too generous on web search and too strict on two-step questions. It lets in 52% of web passages the annotator didn't use (while rejecting 18% of useful ones), but throws out 39% of the paragraphs a two-step question needs (letting in 5% of distractors). With a single sentence that either states the answer or doesn't, both errors stay under 7%.

web search (MS MARCO)18% · 52%
two-step questions (HotpotQA)39% · 5%
single sentences (QNLI)5% · 7%

useful passages rejecteduseless passages let in

How to read this: Each pair of bars is one retrieval task. The first bar is useful passages Jev threw out, the second useless passages it let in. Web search tilts one way, two-step questions the other.

7,237 questions. A likely reason, not measured here: HotpotQA's needed paragraphs are often the 'bridge' that names an entity without stating the answer, and Jev seems to read 'needed' as 'contains the answer'.

In short

  • As a gate for retrieved passages, Jev is too generous on web search, letting in 52% of passages the annotator didn't use.
  • On two-step questions it flips to too strict, throwing out 39% of the paragraphs the answer needs, likely the "bridge" facts.
  • Some web passages it "wrongly" lets in may genuinely help, since MS MARCO marks only the one the annotator happened to use.

What the data shows

work tasks
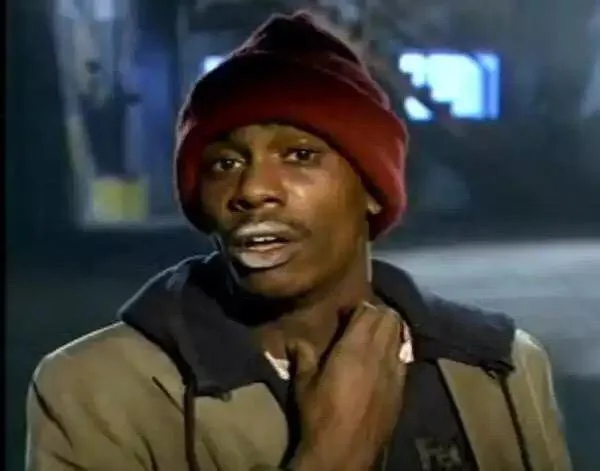
Jev letting 52% of useless web passages into the context
Y'all Got Any More Of That meme: Jev letting 52% of useless web passages into the context
How funny is this meme? Jev: 3/5, funny11%229%366%44%50%
  • Web search: generous. Jev lets in 52% of passages that aren't the annotator's pick, and rejects 18% that are.
  • Two-step questions: strict. It throws out 39% of the paragraphs a question needs, while letting in only 5% of same-topic distractors.
  • Single sentences: balanced. When one sentence either states the answer or doesn't, Jev rejects 5% of useful ones and lets in 7% of useless ones.

What it means, and what it doesn't

As a context gate, Jev's errors depend on the shape of the question. For web search, its generosity mainly costs context space. For multi-step questions it's the opposite risk: it drops the "bridge" facts, which is exactly what makes those questions answerable. Gating for multi-hop answering needs either a looser threshold or a question that asks about intermediate facts.

It doesn't mean Jev can't judge relevance: on the clean single-sentence task both errors are under 7%.

Caveats

  • Web search labels are partial. In MS MARCO, a passage is marked useful if the human annotator used it to write the answer. Other passages that also answer the query are marked not useful, so some of Jev's "let in" errors are passages that do help.
  • "Needed" is subtle for two-step questions. A HotpotQA question often needs a "bridge" paragraph that names an entity without stating the answer. A guess, not measured here, is that Jev reads "needed" as "contains the answer" and throws those out.
  • Question wording. For HotpotQA the question asked whether the passage states a fact needed to answer the question. A wording that mentioned intermediate steps might change the result.

Jev on this experiment

Would a person find it interesting to read?
Yes54%
Does it describe you?
No57%
Would you have predicted it?
No58%
How fair is the comparison?
The comparison is reasonable
How much should a reader rely on it?
A little
Which caveat matters most?
Web search labels are partial58%

Why ask this

Systems that answer questions from documents usually retrieve a pile of passages and then decide which ones go into the expensive model's context. A cheap model as the gate is a natural fit.

Its two kinds of error cost differently. Letting in useless passages wastes context and can distract. Throwing out a useful one can make the right answer impossible, especially for questions that chain two facts: to answer "which company owns the supermarket chain where she worked?", the paragraph naming the chain matters even though it doesn't contain the answer.

How this was done

The people and the data

Three public datasets, 7,237 questions (2,273 from MS MARCO, 2,500 from HotpotQA, 2,464 from QNLI):

  • MS MARCO: real web search queries (from Microsoft) with passages retrieved from web pages; the passage a human annotator used for the answer is marked useful.
  • HotpotQA: questions that need two facts from two Wikipedia paragraphs, mixed with distractor paragraphs on the same topic.
  • QNLI: a question and a single Wikipedia sentence that does or doesn't answer it.

What Jev was asked

Each item was a yes/no question over a passage and a question. For HotpotQA (MS MARCO and QNLI ask "does the passage contain an answer to the query?"):

Should the passage go into the context for answering the question?

The passage states a fact that is needed to answer the question · The passage may be on a related topic, but nothing in it is needed to answer the question

(the question and the passage follow, for example a paragraph about Golub Corporation, the parent company of Price Chopper Supermarkets)

That paragraph is one of the two a question needs; Jev leaned toward leaving it out.

How it was measured

For each dataset, two error rates: the share of useful passages Jev rejects, and the share of useless passages it lets in.

Where these questions live

8,046 questions across 4 topics of the map. Each opens on the map with every question in it.

Every question

All 8,046 questions behind this result, the telling ones first: the examples the analysis points to, then the ones where Jev misses, biggest gap first.

Jev’s own answer
    Showing 0 of 8,046