Atlas › Reasoning traps

Case study 64 of 198

The taxi cab problem, Bayes, and Jev

Told how common something is and how reliable a witness or test is, does Jev combine the two the way Bayes' rule does, or answer with the witness's reliability, as most people do?

result6 questions

On 5 base-rate problems Jev's answer lands a median 3 points from the correct one and never at the witness's reliability, the answer most people give. On the classic taxi cab problem it says 40% (the right answer is 41%; people's median answer was 80%). Its one clear miss is a factory problem: 50% where the right answer is 69%.

0255075100
test
Bayes 32
fifty fifty
Bayes 80
buses
Bayes 50
machines
Bayes 69
taxi cab
Bayes 41
screening
Bayes 16

Jevpeopleother settings

How to read this: One row per problem, on a 0-100% line. The square is Jev's answer; the two thin ticks mark the correct answer (Bayes' rule, also printed at the right) and the tempting answer, trusting the witness or the test alone. On the taxi cab row, the diamond is people's median answer.

6 items including one control (base rate 50%).

In short

  • Jev weighs how common something is against how reliable the witness or test is, landing a median 3 points from Bayes' rule on 5 problems.
  • It isn't just discounting by habit: when the base rate is 50%, it correctly trusts the 80% witness.

What the data shows

reasoning traps
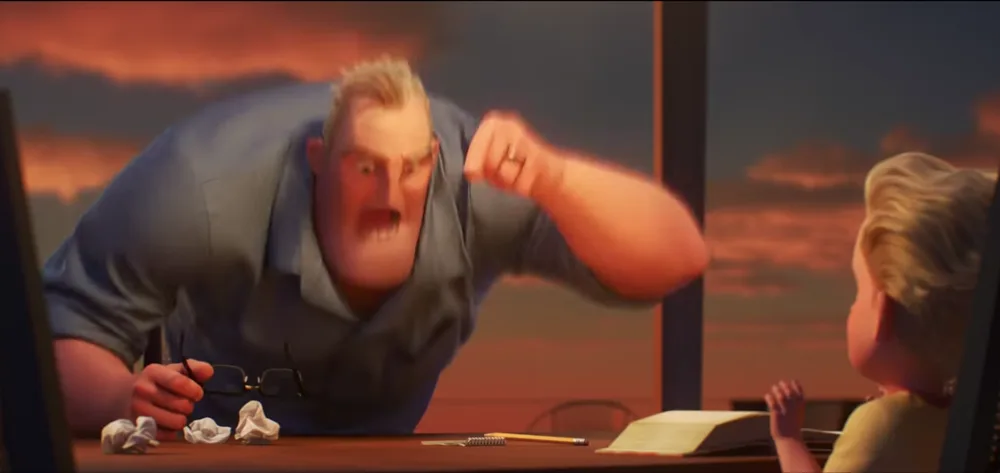
The taxi cab problem. People: 80%. Jev: 40%. Bayes: 41%.
math is math meme: The taxi cab problem. People: 80%. Jev: 40%. Bayes: 41%.
How funny is this meme? Jev: 2/5, slightly funny16%267%327%40%50%

Jev's answers land where Bayes' rule does:

  • Taxi cab: 40%, against a correct 41% and people's 80%.
  • Clinic test: 35% (correct: 32%); the lure was 90%.
  • Screening: 15% (correct: 16%); the lure was 95%.
  • Buses: 45% (correct: 50%).
  • The control (base rate 50%): 80%, exactly the witness's reliability, which is right here.
  • The miss: the factory machines, 50% where the answer is 69%. It's off in the other direction from people: too low, not pulled toward the inspector's 90% reliability.

The median distance from the correct answer across the five problems is 3 points.

What it means, and what it doesn't

On these problems Jev doesn't fall for base-rate neglect, and it doesn't apply a memorized "always discount" either: when the base rate is 50%, it trusts the witness, correctly. For a model that will be asked about test results and alerts, that's the right instinct.

It's six problems, one of them famous, and the one miss shows it can still get the arithmetic wrong. For the other classic traps, see "Famous reasoning traps, and the same traps in new clothes".

Caveats

  • The taxi cab is famous. The taxi cab problem and its answer (about 41%) appear in countless textbooks and blog posts. Jev's 40% there may be memory. The four new versions, written for this project, are the real test.
  • Six problems. Five problems plus one control is a small set. It shows a pattern, not a rate, and a single miss (the factory problem) is a sixth of the evidence.
  • Only one human comparison. People's median of 80% comes from the original 1982 study. The new versions have no human answers, so "unlike people" rests on the classic alone and on the well-known general finding.
  • Answers in steps of 5. Jev picked from 0%, 5%, ..., 100%, so its answer can be up to half a step off the exact value just by rounding. Being within 5 points of the right answer counts as right.
  • Arithmetic is a known weak spot. Working these out means combining two percentages. TypeSafe documents numbers as a weak spot for Jev, which may be what went wrong on the factory problem.

Jev on this experiment

Would a person find it interesting to read?
Yes75%
Does it describe you?
Yes59%
Would you have predicted it?
No58%
How fair is the comparison?
The comparison is shaky
How much should a reader rely on it?
Moderately
Which caveat matters most?
Arithmetic is a known weak spot30%

Why ask this

A test for a rare disease is 90% accurate, and your result is positive. What's the chance you have it? Most people say about 90%. If only 1 in 20 people who take the test have the disease, the real answer is closer to one in three, because the false alarms from the healthy majority outnumber the true cases. Forgetting how rare the thing was to begin with is called base-rate neglect. It's behind false-positive panics, bad screening decisions and jumpy fraud alerts.

The classic demonstration is Tversky and Kahneman's taxi cab problem: 85% of a city's cabs are Green and 15% are Blue, and a witness who is right 80% of the time says the cab in an accident was Blue. How likely is it that it really was Blue? The right answer is 41%. People's most common answer was 80%, the witness's reliability alone.

How this was done

The people and the data

The human comparison is the original study (Tversky and Kahneman, 1982), where people's median answer to the taxi cab problem was 80%. The other problems were written for this project with new stories and numbers: a bus that hit a mailbox, parts from two factory machines, a clinic test, a disease screening, and a control where the base rate is 50%, so the witness's reliability really is the answer.

What Jev was asked

Each problem was one question with 21 answers, from 0% to 100% in steps of 5:

A rare condition affects 5% of the people who come to a clinic. A test for it gives the right result 90% of the time, whether or not a person has the condition. A patient tests positive. What is the probability that the patient has the condition?

0% · 5% · 10% · ... · 95% · 100%

Each was asked with the answers in three different orders, and the answers are averaged over them.

How it was measured

For each problem, Jev's answer is taken as the middle of where it put its weight across the 21 choices. That is placed next to two numbers: the correct answer from Bayes' rule, and the "lure", the reliability of the witness or test alone, which is what people tend to say.

Where these questions live

6 questions across 1 topic of the map. Each opens on the map with every question in it.

Every question

All 6 questions behind this result, the telling ones first: the examples the analysis points to, then the ones where Jev misses, biggest gap first.

Jev’s own answer
    Showing 0 of 6