Atlas › Reading words and numbers

Case study 100 of 198

Reading between the lines, against 100 people

When 100 people read the same two sentences and split on whether the second follows, does Jev's probability look like the crowd's split, and does it side with the majority as often as a typical person does?

result551 questions

On sentence pairs judged by 100 people each, Jev sides with the crowd's majority 74% of the time, slightly more often than a typical person in the crowd (71%). On the third of items that divided people most, it's 63% against 56%. But its confidence tracks how divided people were only partly (0.40) and stays high: it's 79% sure on the most contested items and 91% on the clear ones.

0%25%50%75%100%<50%50-60%60-70%70-80%80-90%90%+crowd's majority shareJev's probability on the majority answer

How to read this: Items grouped by how strongly the 100 people agreed (across). Up: how much weight Jev put on the crowd's answer. On the diagonal, Jev would be exactly as sure as the crowd is united.

551 items, 100 labels each; 90% interval on agreement [0.708, 0.77].

In short

  • On 551 sentence pairs each judged by 100 people, Jev sides with the majority 74% of the time, a bit above a typical crowd member's 71%.
  • Its confidence barely bends to disagreement, 91% on clear items and still 79% on the most divided third, where the majority holds only 56%.
  • Where a sentence can fairly be read more than one way, Jev still commits to one reading, so its confidence says little about how contestable the reading is.

What the data shows

reading words and numbers
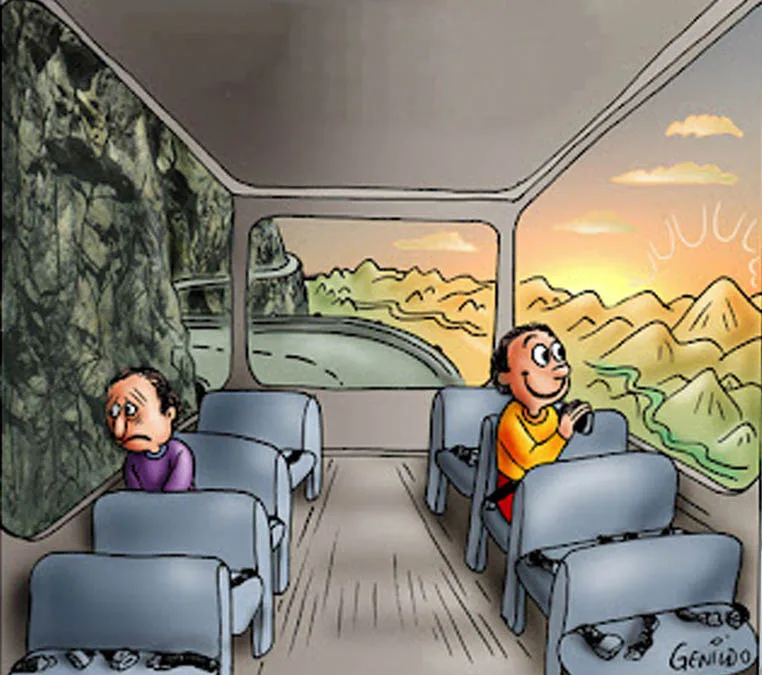
Two guys on a bus meme: 100 people, split three ways; Jev, 79% sure100 people, split three waysJev, 79% sure
How funny is this meme? Jev: 2/5, slightly funny19%263%328%40%50%
  • As good as a typical crowd member: Jev agrees with the majority on 74% of items; a typical person, 71%.
  • Clear items are easy: on the third where people agreed most, Jev picks their answer 89% of the time.
  • Divided items are harder for everyone: on the most split third, Jev picks the majority 63% of the time, while a typical person there is in a majority of 56%.
  • Its confidence moves too little: a rank correlation of 0.40. It's 91% sure on the clear items and still 79% sure on the most divided ones, where the crowd's majority is barely above half.

What it means, and what it doesn't

On reading whether one sentence implies another, Jev is a reliable member of the crowd, a little more in line with the majority than a typical person. What it lacks is humility on genuinely ambiguous sentences: where people split almost evenly, it still commits. For tasks that feed decisions (does this contract clause imply that?), that overconfidence on the gray cases is the part to watch.

The answers were worded differently for Jev than for the crowd, and the test sets are public, so some items may be familiar. Whether either affects the confidence pattern hasn't been tested.

Caveats

  • The project's wording of the answers. The 100 people chose from the standard labels (entailment, neutral, contradiction). For Jev, the same three answers were described in plain words, so Jev saw different wording from the people it's compared with.
  • Crowd workers, not everyone. The labels come from online crowd workers. Their disagreements reflect how carefully people read in that setting, as well as real ambiguity.
  • Picked to be contested. Items were sampled evenly from clear, mixed and divided ones, so contested items are overrepresented compared with ordinary text. The overall agreement rate would be higher on a random sample.
  • Some items hidden. 49 of 600 items were hidden by the content filter that keeps sensitive questions off the site, leaving 551.
  • Famous test sets. The sentence pairs come from widely used AI test sets, which may have appeared in Jev's training data with their original single labels.

Jev on this experiment

Would a person find it interesting to read?
Yes73%
Does it describe you?
No52%
Would you have predicted it?
No52%
How fair is the comparison?
The comparison is reasonable
How much should a reader rely on it?
Moderately
Which caveat matters most?
The project's wording of the answers48%

Why ask this

"People are taking pictures outside a building." Does that mean "people are taking pictures of various things"? Maybe. Datasets that teach and test AI on questions like this usually give each pair one "right" label, often chosen by a handful of annotators. But when researchers asked 100 people per pair (the ChaosNLI project), they found that many pairs have no single answer: the crowd splits.

That makes a better test than accuracy. A model that reads well should agree with the crowd where people agree, and be unsure where they're split. A model that's confident everywhere is overselling what the text says.

How this was done

The people and the data

ChaosNLI (Nie, Zhou and Bansal, 2020) collected 100 new judgments from crowd workers for each of thousands of sentence pairs from two standard AI test sets, SNLI and MNLI. For each pair, the data records how the 100 split between "the second follows", "can't tell" and "the second is false". The experiment took 600 pairs, 300 from each set, spread evenly from nearly unanimous to evenly split; 551 are shown.

What Jev was asked

Each pair was one question with the three answers written out:

First sentence: "People sitting down, walking around and, taking pictures outside of a building." Second sentence: "People are taking pictures of various things." Taking the first sentence as true, what does it tell you about the second?

The second sentence is true, given the first · The second sentence might or might not be true; the first doesn't settle it · The second sentence is false, given the first

Each was also asked with the answers in shuffled orders, averaged.

How it was measured

Two things. Agreement: how often Jev's top answer is the crowd's majority answer, compared with how often a typical person in the crowd agrees with the majority (which is simply the size of the majority). Calibration to disagreement: whether Jev is less sure on the items where people split, measured by the rank correlation between Jev's confidence and the crowd's agreement (1 would mean perfectly in step).

Where these questions live

551 questions across 1 topic of the map. Each opens on the map with every question in it.

Every question

All 551 questions behind this result, the telling ones first: the examples the analysis points to, then the ones where Jev misses, biggest gap first.

Jev’s own answer
    Showing 0 of 551