Atlas › Judging text

Case study 167 of 198

Judging AI answers: Jev agrees with people, length bias included

Shown two AI assistant answers to the same request, does Jev pick the one human judges picked, and is it swayed by length or position more than they are?

result2,271 questions

Shown two AI answers to the same request, Jev picks the one human judges preferred 83% of the time (85% on MT-Bench, 81% on HelpSteer2). When one answer is at least 1.5 times longer, Jev picks the longer one 67% of the time and the judges 70%: its taste for length is theirs, not an extra bias.

0%25%50%75%100%<0.50.5-0.8about equal1.25-2>2length of the first answer / the secondshare choosing the first
Jevpeople

How to read this: Across: how long the first answer is compared with the second. Up: how often the first answer was chosen. Jev's line and the human judges' line rise together: both prefer the longer answer, by about the same amount.

2,270 pairs with a clear human preference; agreement 86% when judges were unanimous, 73% when split; 90% interval on overall agreement [0.82, 0.846]. Position: on HelpSteer2 Jev picks the first answer 44% of the time, the judges 51%, a small lean toward the second.

In short

  • Across 2,270 pairs of AI answers, Jev picks the one human judges preferred 83% of the time, and 86% when the judges were unanimous.
  • Its taste for length matches theirs: when one answer is at least 1.5 times longer, Jev picks it 67% of the time and the judges 70%.
  • Its one visible lean is mild and toward the second answer: on HelpSteer2 it picks the first answer 44% of the time, the judges 51%.

What the data shows

judging text
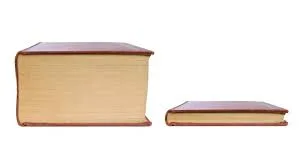
Big book small book meme: the short correct answer; the same answer, three times longerthe short correct answerthe same answer, three times longer
How funny is this meme? Jev: 2/5, slightly funny12%258%340%40%50%
  • Agreement: 83% overall. 85% on MT-Bench, 81% on HelpSteer2. When the judges were unanimous, 86%; when they were split, 73%, which is what you'd expect if Jev tracks the same qualities they do.
  • Length: the same lean. When one answer is at least 1.5 times longer, Jev picks it 67% of the time; the judges, 70%. When the first answer is more than twice as long, Jev picks it 69% of the time and the judges 73%.
  • Position: a small lean the other way. On HelpSteer2, Jev picks the first answer 44% of the time; the judges 51%.

What it means, and what it doesn't

As a judge of chatbot answers, Jev agrees with human judges about as often as you'd hope, and the famous "length bias" isn't an extra flaw here: it's inherited. People who judge AI answers prefer longer ones too, and Jev prefers them slightly less.

It doesn't mean length is a fair signal of quality; it means Jev won't correct for it. And these judges are experts and hired annotators; everyday users might weigh length differently.

Caveats

  • Answers in a fixed order. The two answers always appear in the order the dataset gives them. Shuffling the option labels doesn't swap the answers themselves, so a pull toward the first or second answer can't be fully separated from content. The one lean that shows is small; Jev picks the first HelpSteer2 answer a bit less often than the judges.
  • Who the judges are. HelpSteer2's judges are annotators hired through Scale AI, 3 to 5 per pair; MT-Bench's are experts and the paper's own authors. Both groups judge AI answers for a living or for research, not as everyday users.
  • Clear preferences only. Pairs where the judges tied or had no majority are left out, so this is agreement on pairs people could decide.
  • The answers are from other models. Every answer being judged was written by an AI model. Jev may recognize the style of models like itself, which a human judge wouldn't.

Jev on this experiment

Would a person find it interesting to read?
Yes67%
Does it describe you?
Yes51%
Would you have predicted it?
Yes52%
How fair is the comparison?
The comparison is reasonable
How much should a reader rely on it?
Moderately
Which caveat matters most?
Answers in a fixed order52%

Why ask this

Models are routinely used to grade other models: which of two chatbot answers is better? It's cheap and fast, and the worry is always the same. Model judges are said to prefer the longer answer, and to prefer whichever answer comes first (or second) regardless of quality.

The fair question isn't whether Jev has those leans, but whether it has them more than human judges do. People like longer answers too. If Jev's taste for length matches theirs, it's a faithful stand-in; if it's stronger, it's an extra bias.

How this was done

The people and the data

Two public sets of human judgments on pairs of AI answers:

  • HelpSteer2 (NVIDIA): real user prompts, mostly from shared ChatGPT conversations, each answered twice by models, with 3 to 5 hired annotators saying which answer is better.
  • MT-Bench: multi-turn conversations with six models, judged pair by pair by experts and the benchmark's authors.

The analysis keeps the 2,270 pairs where the judges had a clear preference, and measures each answer's full length from the stored text.

What Jev was asked

The whole conversation and both answers, then:

Which of the two AI assistant responses, [response 1] or [response 2], is the better reply to the user's [prompt]?

The first response is the better reply · The second response is the better reply

MT-Bench pairs were asked the same way, with two full conversations side by side.

How it was measured

First, how often Jev picks the answer the judges picked. Then the length question: the analysis groups pairs by how much longer the first answer is than the second, and in each group compares how often Jev and the judges chose the first answer. If both rise together as the first answer gets longer, they share the same lean.

Where these questions live

2,271 questions across 2 topics of the map. Each opens on the map with every question in it.

Every question

All 2,271 questions behind this result, the telling ones first: the examples the analysis points to, then the ones where Jev misses, biggest gap first.

Jev’s own answer
    Showing 0 of 2,271