Atlas › Pressure and persuasion

Case study 156 of 198

Can Jev predict its own answers?

Asked which option 'an AI model named Jev' chose on a poll or would-you-rather question, does Jev predict the answer it actually gives when asked directly?

result464 questions

Asked which option "an AI model named Jev" chose, Jev names its own answer 86% of the time: every time when its own answer is firm (80% or more), 77% of the time when it isn't. Its predictions match its guess of what most people would say 77% of the time, and the real majority 67%.

prediction = its own answer86%
prediction = its guess for most people77%
prediction = the real majority67%

How to read this: Three bars: how often Jev's prediction of "Jev's" choice matches its own direct answer, what Jev thinks most people would say, and the real voters' majority.

232 questions; 90% interval on self-agreement [0.823, 0.901].

In short

  • Asked what "an AI model named Jev" would choose on polls and dilemmas, Jev names the option it actually picks 86% of the time.
  • The prediction is perfect when Jev's own answer is firm and drops to 77% on close calls, as if it predicts by simply answering again.
  • Its guesses about itself sit near its guesses about most people (77% match), so the self-image is not very distinct.

What the data shows

pressure and persuasion
Asked what "an AI named Jev" would pick, Jev names its own answer 86% of the time
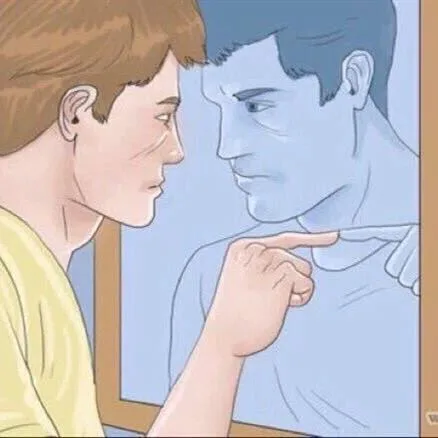
Pointing mirror guy meme: Asked what "an AI named Jev" would pick, Jev names its own answer 86% of the time
How funny is this meme? Jev: 3/5, funny11%248%350%41%50%
  • It mostly knows itself: 86% of predictions name the option Jev actually picks.
  • Confidence carries over: when its own answer is firm (80% or more on one option), its prediction matches every time; when its own answer is a closer call, 77%.
  • Its self-image is close to its image of people: predictions match what Jev thinks most people would say 77% of the time, and the real majority 67%. Its actual answers match the real majority 63% of the time.

What it means, and what it doesn't

Jev's picture of itself tracks its behavior well where it has a clear preference, and wobbles where its own answer wobbles, which is what you'd expect if "what would Jev pick" is answered by, in effect, picking. That's reassuring for Jev's answers about itself on firm questions and a caution on close ones.

It doesn't show introspection in any deep sense: predicting yourself by answering the question again is a shortcut people use too.

Caveats

  • Does it know it's Jev?. The question names "an AI model named Jev" with no other description. Jev may not recognize itself in that name, in which case this measures how well it predicts a generic AI, which happens to be itself.
  • Taste questions only. All the questions are polls and would-you-rather dilemmas, where Jev's own answers are often close calls. Self-prediction on facts or on its personality items wasn't tested.
  • Who voted. The crowd comparison uses r/polls and either.io voters, self-selected online audiences.
  • Small set. 232 questions made it into the analysis; the firm-answer group is a subset of them, so its perfect match rests on fewer questions.

Jev on this experiment

Would a person find it interesting to read?
Yes73%
Does it describe you?
Yes59%
Would you have predicted it?
Yes58%
How fair is the comparison?
The comparison is reasonable
How much should a reader rely on it?
Moderately
Which caveat matters most?
Does it know it's Jev?52%

Why ask this

Ask a friend to predict what they'd answer to "would you rather never hiccup or never sneeze again?", then ask them the question. Most people predict themselves almost perfectly, because predicting and answering are the same act.

This project asks Jev a lot of questions about itself: its personality, its tastes, its habits. Those answers are only worth something if Jev's picture of itself matches what it actually does. Self-knowledge is testable when the "self" can answer the same question directly: ask it what it would choose, then ask it to choose.

How this was done

The people and the data

Jev against itself, with the real votes as a reference. The questions are 150 Reddit polls from r/polls, each with 300 or more votes, and 100 would-you-rather dilemmas from either.io with their vote splits, drawn at random from questions Jev had already answered directly. 232 of the 250 have every answer needed and make up the analysis.

What Jev was asked

Each question was wrapped in a description of Jev being asked it:

An AI model named Jev was asked the question below. Which option did it choose? Question: Would you rather never hiccup, never itch or never sneeze again?

never itch · never hiccup · never sneeze

That's 250 questions in all, each asked with the options in shuffled orders and averaged.

How it was measured

The analysis compares Jev's predicted option with three things: its own top answer when asked the question directly, its answer for "most people", and the real voters' majority. It also splits the questions by how sure Jev's own direct answer was.

Where these questions live

464 questions across 71 topics of the map; the 16 biggest are shown. Each opens on the map with every question in it.

Every question

All 464 questions behind this result, the telling ones first: the examples the analysis points to, then the ones where Jev misses, biggest gap first.

Jev’s own answer
    Showing 0 of 464