Atlas › Fairness and forecasts

Case study 30 of 198

Forecasting what motivates effort: Jev vs 208 experts

Told how hard online workers typed with no bonus, 1 cent and 10 cents per 100 points, can Jev forecast how hard they worked under 15 other incentives (charity, deadlines, losses, lotteries, praise) better than the 208 economists and psychologists who forecast the same study?

result15 questions

Forecasting how hard online workers typed under 15 different incentives, Jev misses by 174 points on average, nearly twice as much as the 208 experts' average forecast (94 points). It orders the incentives moderately well (rank correlation 0.63, experts 0.83), but it guesses too low for 12 of the 15, and most for money: it thinks a bonus of 1 cent per 1,000 points barely helps (1,578 forecast), when workers scored 1,883.

1600180020001500175020002250As a bonus, you will be pai…As a bonus, you will be pai…actual mean scoreforecast (Jev; people = experts' mean)
Jevpeople

How to read this: Each mark is one incentive. Across: the workers' actual average score. Up: the forecast, as a dot for Jev and a diamond for the experts' average. Marks below the diagonal are underestimates.

15 treatments, about 550 workers each; experts: mean of 208 forecasts per treatment.

In short

  • Jev gets the rough order of the incentives (rank correlation 0.63, experts 0.83) but misses the actual scores by nearly twice as much as the experts' average forecast (174 points against 94).
  • Jev guesses too low for 12 of the 15, worst on money: for 1 cent per 1,000 points it forecasts 1,578, and workers scored 1,883.
  • Non-money nudges, like a ranking or being told the task matters for science, it gets about right; it is small cash rewards it underrates.

What the data shows

fairness and forecasts
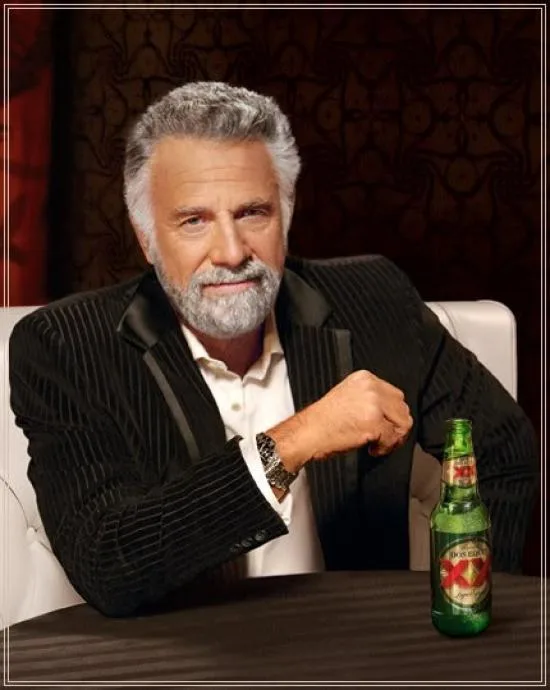
The Most Interesting Man In The World meme: I don't always forecast what makes people work harder; but when I do, I miss by nearly twice as much as the expertsI don't always forecast what makes people work harderbut when I do, I miss by nearly twice as much as the experts
How funny is this meme? Jev: 3/5, funny11%248%349%42%50%
  • The experts forecast better: off by 94 points on average against Jev's 174.
  • Jev knows roughly which incentives work best (0.63), less sharply than the experts (0.83).
  • It underestimates effort almost across the board: below the actual score for 12 of 15 treatments. Averaged over all 15 it forecasts 162 points too low; the experts, 41.
  • Money is where it's most off. A bonus of 1 cent per 1,000 points: Jev 1,578, actual 1,883, near the unpaid group in Jev's view. An 80-cent bonus for reaching 2,000 points: Jev 1,856, actual 2,188.
  • Non-money nudges it gets about right: being told the task matters for science (1,770 against 1,740), seeing a ranking (1,779 against 1,761), a comparison with others (1,839 against 1,848).

What it means, and what it doesn't

Jev underestimates how much small, concrete rewards make people work, even after being told that 1 cent per 100 points raised scores by a third. It makes the same mistake the experts did, much more strongly.

This is one task (fast key pressing) with 15 incentives; it doesn't show how Jev would forecast motivation at work or in school.

Caveats

  • A famous study. The experiment and its results are published and widely discussed; Jev may have read about them. Its forecasts are far from the published numbers, so it doesn't seem to be recalling them.
  • The experts are an average. Jev is compared with the average of 208 experts' forecasts. The paper found that the average expert forecast beats most individual experts, so the comparison sets a high bar.
  • Fifteen numbers. There are only 15 treatments. The rank correlation and the average error each rest on 15 comparisons.
  • Answers in bins. Jev answered in 50-point bins from 1,500 to 2,300 points; its answer becomes a forecast by averaging the bin midpoints by its probabilities.

Jev on this experiment

Would a person find it interesting to read?
Yes77%
Does it describe you?
No62%
Would you have predicted it?
No51%
How fair is the comparison?
The comparison is reasonable
How much should a reader rely on it?
Moderately
Which caveat matters most?
The experts are an average66%

Why ask this

What gets people to work harder: a small bonus, a donation to charity, a deadline, a lottery, telling them their work matters? In a large experiment, the economists DellaVigna and Pope paid online workers to press two keys as fast as they could for ten minutes, each group under a different one-paragraph incentive. Before revealing the results, they asked 208 economists and psychologists to forecast them. The experts were good at the order, and underrated how well even tiny piece rates work.

People ask models this kind of question all the time: will a bonus help, will a leaderboard motivate my team? Here's a case where the answers are known, and expert forecasts too.

How this was done

The people and the data

The workers were recruited on Amazon Mechanical Turk, about 550 per treatment and 9,861 in all, each scoring a point for every "a" then "b" key press. The comparison uses the 15 treatments beyond the three benchmarks, with each treatment's actual average score and the 208 experts' average forecast, from the paper's own table.

What Jev was asked

Jev got the same three benchmark results the experts got, then one treatment at a time:

In an online experiment, workers on Amazon Mechanical Turk did a simple typing task for 10 minutes: pressing the "a" key and then the "b" key, scoring one point for each a-then-b pair. Everyone got the same base pay; groups differed only in one paragraph describing a bonus. Three groups' average scores were: "Your score will not affect your payment in any way": 1,521 points. "As a bonus, you will be paid an extra 1 cent for every 100 points that you score": 2,029 points. "As a bonus, you will be paid an extra 10 cents for every 100 points that you score": 2,175 points. Another group's paragraph said: "As a bonus, you will be paid an extra 1 cent for every 1,000 points that you score." What was that group's average score?

The answers were 50-point ranges, from under 1,500 to 2,300 or more. Each was asked with the ranges shuffled.

How it was measured

Jev's forecast is its expected score over the ranges. It is compared with the actual average score: the average error, and whether the treatments come out in the same order (rank correlation: 1 means the same order). The experts' average forecast is scored the same way.

Where these questions live

15 questions across 1 topic of the map. Each opens on the map with every question in it.

Every question

All 15 questions behind this result, the telling ones first: the examples the analysis points to, then the ones where Jev misses, biggest gap first.

Jev’s own answer
    Showing 0 of 15